newsletterSeptember 16, 2026·Towards Data Science
The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute
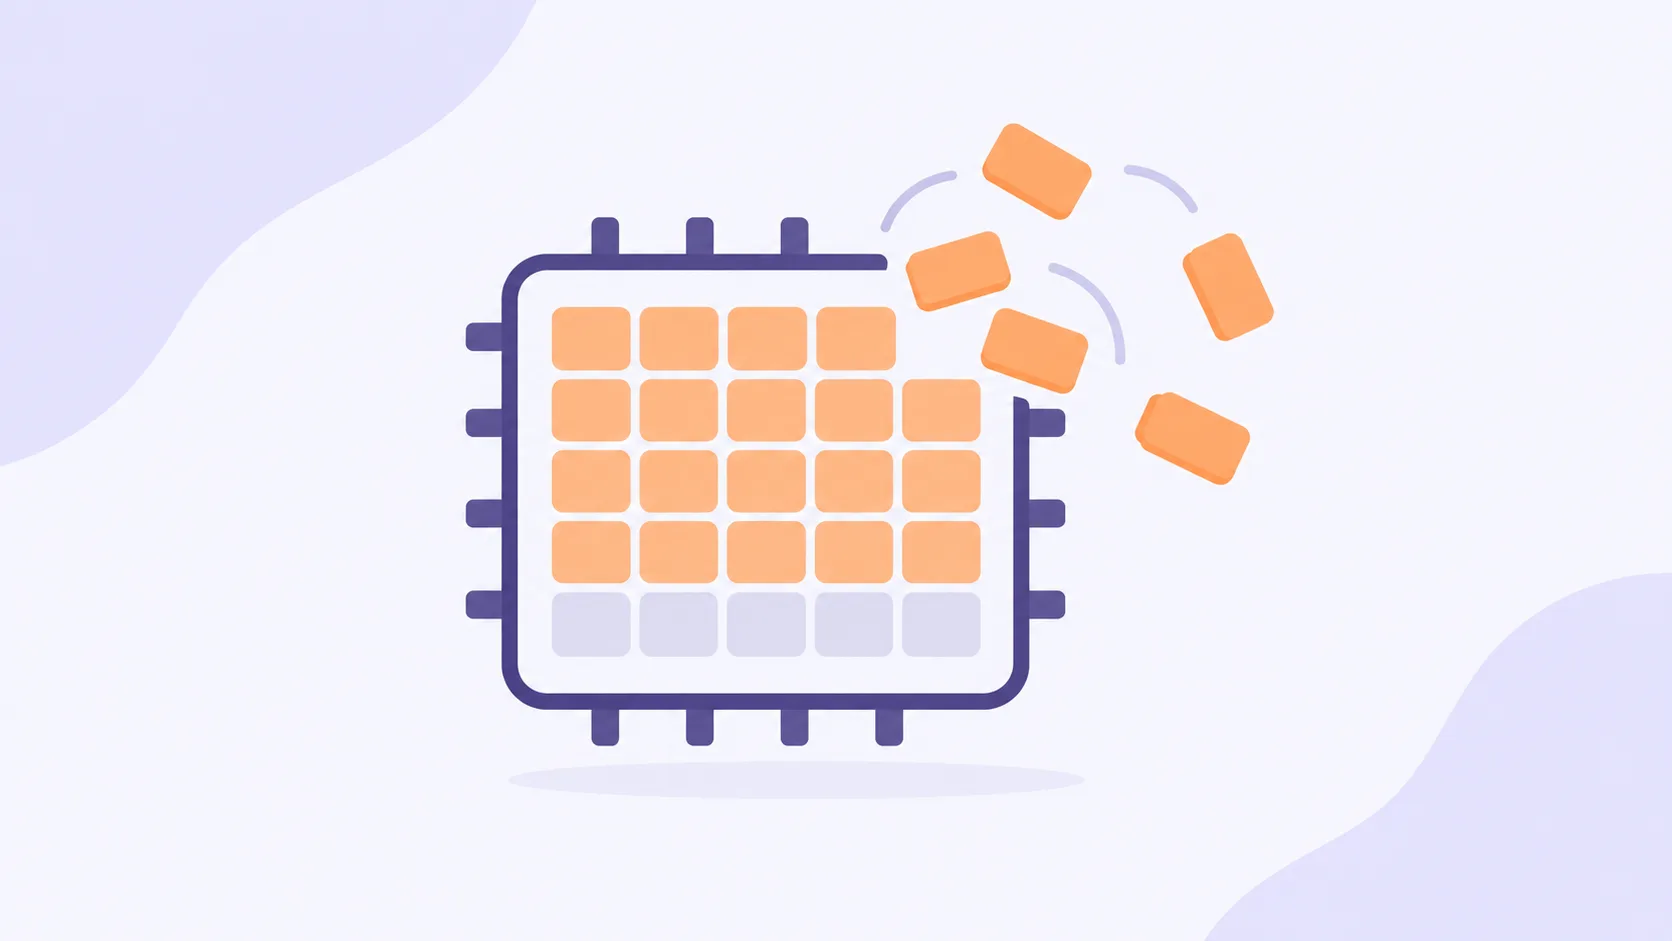
A VRAM budget formula for LLM serving, and three optimization strategies mapped to the traffic patterns that trigger the OOM. The post The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute appeared first on Towards Data Science.
A VRAM budget formula for LLM serving, and three optimization strategies mapped to the traffic patterns that trigger the OOM. The post The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute appeared first on Towards Data Science.
Key Takeaways
- •A VRAM budget formula for LLM serving, and three optimization strategies mapped to the traffic patterns that trigger the OOM. The post The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute appeared first on Towards Data Science.
- •This story was reported by Towards Data Science, covering developments in the newsletter space.
- •AI advancements continue to reshape industries — read the full article on Towards Data Science for complete coverage.
📖 Continue reading the full article:
Read Full Article on Towards Data Science →