tutorialNovember 12, 2026·ML Mastery
Fast Attention Kernels and Operator Fusion
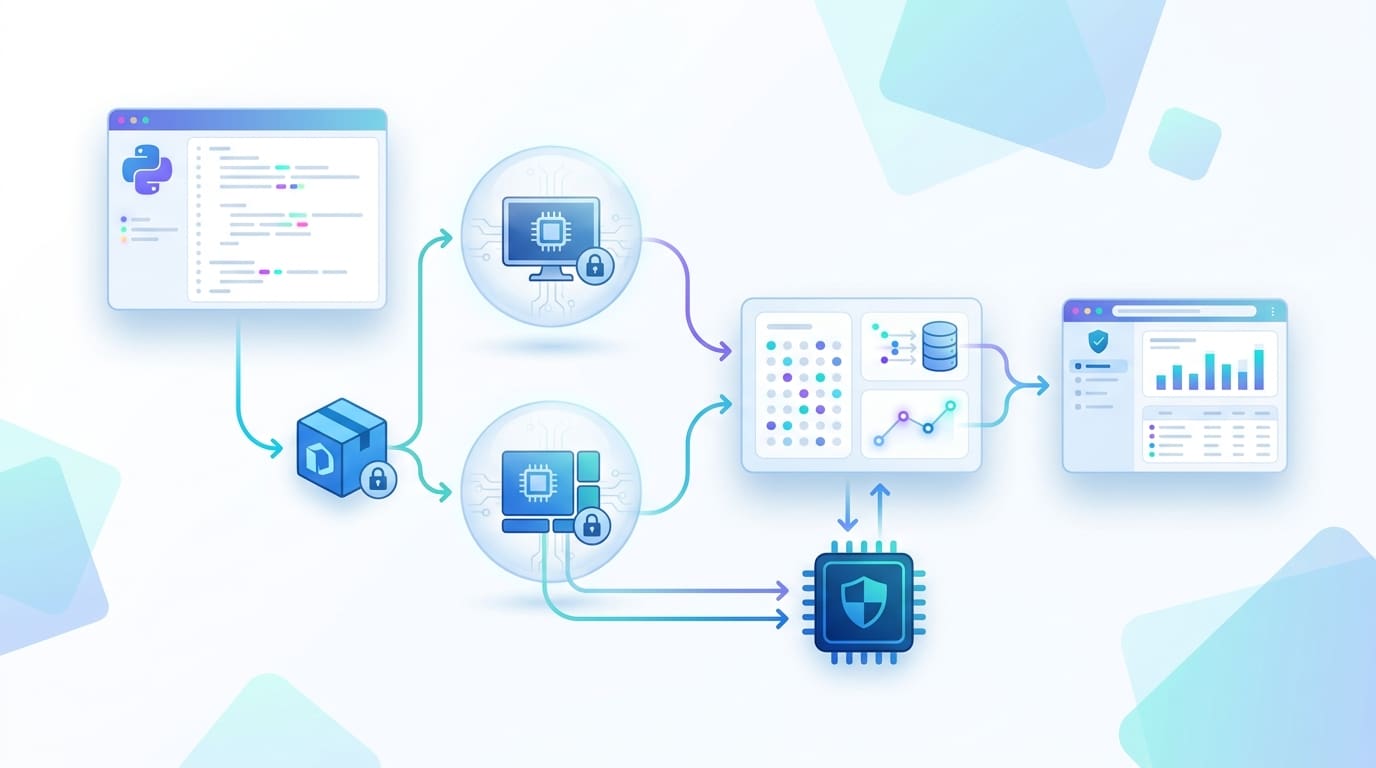
Overview This post is divided into four parts; they are: • Operator Fusion • FlashAttention-Style Kernels • Paged Attention Kernels • Fusion and CUDA Graphs with torch.
Overview This post is divided into four parts; they are: • Operator Fusion • FlashAttention-Style Kernels • Paged Attention Kernels • Fusion and CUDA Graphs with torch.
Key Takeaways
- •Latest on Fast Attention Kernels and Operator Fusion — reported by ML Mastery for the tutorial space.
- •This story was reported by ML Mastery, covering developments in the tutorial space.
- •AI advancements continue to reshape industries — read the full article on ML Mastery for complete coverage.
📖 Continue reading the full article:
Read Full Article on ML Mastery →